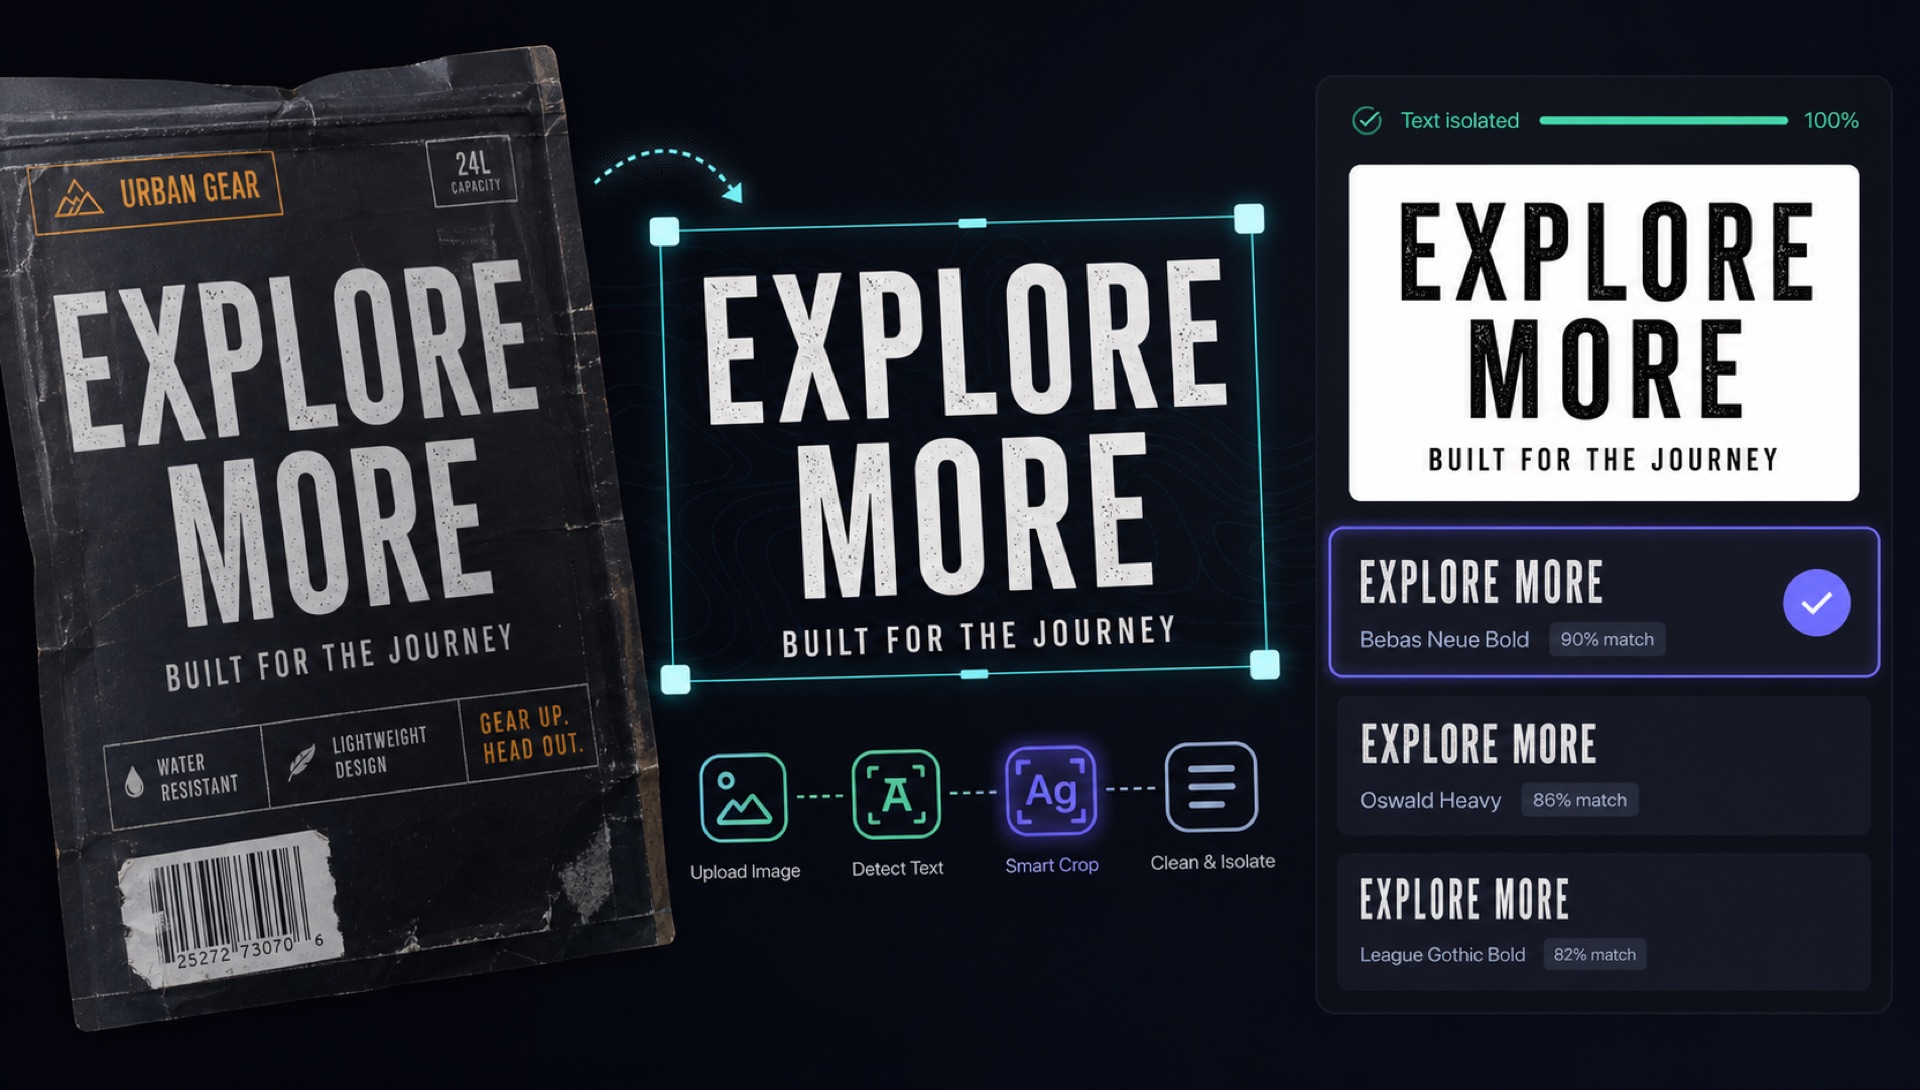
A company logo usually contains both a symbol and text. A screenshot might include navigation bars, buttons, and multiple typographic hierarchies. A product photo has decorative elements, photography, and perhaps a dozen fonts competing for attention.
FontFinder's smart cropping step solves a fundamental challenge: finding the text region that the user actually cares about, and cropping to exactly that region.
The Challenge
If we feed a full logo image to our AI model, it has to process the icon, the brand mark, the decorative elements, and the text all at once. The text — the part that contains font information — might occupy only 20% of the image. The rest is noise from the model's perspective.
Step 1: Morphological Dilation
Individual characters are separated by small gaps. The letter 'H' consists of two vertical strokes and a crossbar — three distinct components. A word like "FontFinder" has many separate connected components (one per letter, approximately).
We use morphological dilation with a horizontal structuring element to connect nearby components into unified text blobs. The kernel width is tuned to connect characters within the same word while not connecting words from different text lines.
Step 2: Contour Detection
After dilation, we run OpenCV's contour detection to find all connected regions in the binarised image. We filter contours by aspect ratio and area — text blocks have characteristic proportions that distinguish them from icons, decorative elements, and noise artifacts.
Step 3: Bounding Box Selection
From the filtered contours, we compute bounding boxes and score them based on:
- Area — larger text regions are preferred
- Aspect ratio — text is typically wider than tall
- Edge density — text has high edge density (many character strokes)
- Position — central regions are preferred over edge regions
Step 4: Padding and Letterboxing
After cropping to the text bounding box, we add a small padding margin (10% of each dimension) to ensure no character strokes are cut off. Then we resize to our model's input dimensions (224×224) using letterbox scaling — adding white borders rather than distorting the aspect ratio.
Tuning the Dilation Kernel
Step one hides the most delicate decision in the whole pipeline: how wide to make the structuring element. The kernel has to be wide enough to bridge the gap between adjacent letters, but narrow enough that it does not bridge the gap between adjacent words — or worse, between a headline and the subtitle beneath it.
Those gaps are not fixed quantities. They scale with the type size, and their ratio varies by typeface. A condensed grotesque sets letters tightly and words tightly; a wide display face with generous tracking may put more space between two letters of the same word than a condensed face puts between two words. A kernel calibrated on one will merge the other into a single blob.
We handle this by deriving the kernel width from the image rather than fixing it. After binarisation we estimate the dominant stroke width from the connected components, and scale the structuring element relative to that. Stroke width is a reasonable proxy for type size, so the kernel grows and shrinks with the letters instead of with the image dimensions.
Why Aspect Ratio Alone Is a Weak Filter
Filtering contours by proportion catches most non-text regions, but it has predictable false positives and false negatives worth understanding.
- False positives: horizontal rules, underlines, progress bars, and table borders all have exactly the wide-and-short profile that text has. Edge density is what separates them — a rule has two long edges, whereas a word has dozens of short ones.
- False negatives: a single short word, a stacked logotype, or vertically-set text fails the wider-than-tall test entirely despite being exactly what the user wants identified.
This is why the scoring step combines four signals rather than thresholding on any one of them. No individual feature is reliable enough to act alone, but a region that is large, reasonably proportioned, dense with edges, and near the centre of frame is text with high probability.
Letterboxing, and Why We Never Stretch
The final resize to 224×224 is where a subtle but serious mistake is easy to make. Squashing a wide crop into a square input changes the width-to-height ratio of every glyph — and that ratio is one of the strongest signals distinguishing one typeface from another. A condensed grotesque stretched to fit a square is, to the model, simply a different font.
Letterboxing preserves the aspect ratio and fills the remainder with white. The model sees fewer pixels of actual text, which costs a little resolution, but the letterforms retain their true proportions. That trade is heavily worth making: proportion is signal, and resolution beyond a point is not.
Manual Override: The Crop Tool
Automatic cropping works for most images, but some logos and designs are complex enough to fool our algorithm. That's why FontFinder also gives users a manual crop tool — draw a box around exactly the text you want identified, and that region goes directly to the model, bypassing the automatic cropping entirely.
It is worth reaching for the manual tool deliberately in three situations: when the image contains several typefaces and you want a specific one; when the text you care about is small relative to a busy background; and when the automatic result clearly grabbed a logo mark instead of the wordmark. In each case the algorithm is not malfunctioning — it is choosing the most text-like region, which is not always the region you meant. A human crop resolves the ambiguity instantly.